Keep your job: the best AI agent finished 30% of the office work.
The best AI agent finished 30% of the tasks at a simulated software company.
We didn’t run this. TheAgentCompany: Benchmarking LLM Agents on Consequential Real World Tasks (arXiv 2412.14161, v3) did. ModelSignal read the published work and checked every number below against it — the sources and the dates we read them are at the end.
AI agents · 175 office tasks
30%
of the work got done.
By the best AI agent.
Carnegie Mellon's TheAgentCompany test, 2025.
Best vs worst
 OpenAI's GPT-4o
8.6%
Tasks finished
With partial credit16.7%
 Gemini 2.5 Pro
30.3%
Tasks finished
Cost per task$4.2
Mind the gap.
The best agent finished under a third of the work. The rest needed a human.
CMU + Duke · 175 tasks · 7 models
The proof
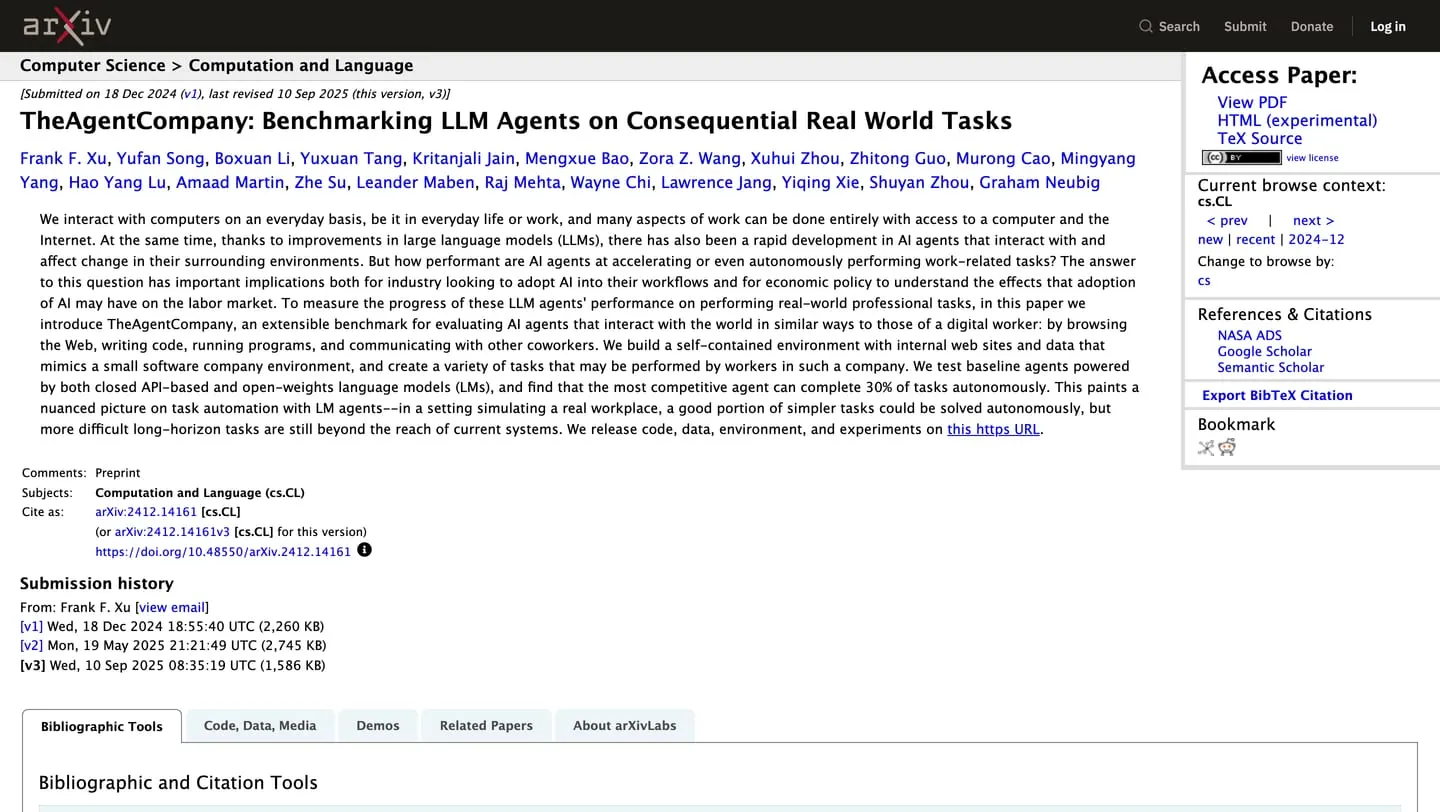
CMU and Duke's paper on arXiv, Sept 2025. Read 13 Oct 2026.
The full breakdown
Somebody else ran this experiment; we read it. Every number below is quoted from the paper, with the date we read it.
The benchmark
TheAgentCompany, by researchers at Carnegie Mellon University and Duke University: "a self-contained environment with internal web sites and data that mimics a small software company environment", with 175 tasks (browsing, coding, running applications, communicating with coworkers). Agents ran on the OpenHands framework.
Results (Table 1, version 3, September 2025)
| Model | Done | With partial credit | Avg steps | Cost per task |
|---|---|---|---|---|
| Gemini 2.5 Pro | 30.3% | 39.3% | 27.2 | $4.2 |
| Claude 3.7 Sonnet | 26.3% | 36.4% | 27.8 | $4.1 |
| Claude 3.5 Sonnet | 24.0% | 34.4% | 29.2 | $6.3 |
| Gemini 2.0 Flash | 11.4% | 19.0% | 39.9 | $0.6 |
| GPT-4o | 8.6% | 16.7% | 14.6 | $1.3 |
| Llama 3.1 405B | 7.4% | 14.1% | 23.0 | $3.2 |
| Llama 3.3 70B | 6.9% | 12.8% | 20.9 | $0.9 |
Sources
The catches
- A benchmark in a simulated company, scored on task completion, not on the quality of the work.
- Agents ran on the OpenHands framework; another scaffold could score differently.
- Results are for the models listed as of September 2025; newer models were not in the table we read.
Every number, and where it’s quoted from
- the best agent completes 30% of tasks“the most competitive agent can complete 30% of tasks autonomously”arXiv 2412.14161 abstract
- 175 tasks“Total Tasks: 175”arXiv 2412.14161v3
- Gemini 2.5 Pro 30.3% success, 39.3% partial, 27.2 steps, $4.2 per task“Gemini-2.5-Pro | OpenHands 0.28.1 | 30.3% | 39.3% | 27.2 | $4.2”arXiv 2412.14161v3 Table 1
- Claude 3.7 Sonnet 26.3% / 36.4%“Claude-3.7-Sonnet | 26.3% | 36.4%”arXiv 2412.14161v3 Table 1
- Claude 3.5 Sonnet 24.0% / 34.4%“Claude-3.5-Sonnet | 24.0% | 34.4%”arXiv 2412.14161v3 Table 1
- Gemini 2.0 Flash 11.4%“Gemini-2.0-Flash | 11.4% | 19.0%”arXiv 2412.14161v3 Table 1
- GPT-4o 8.6% / 16.7%“GPT-4o | 8.6% | 16.7%”arXiv 2412.14161v3 Table 1
- Llama 3.1 405B 7.4% / 14.1%“Llama-3.1-405b | 7.4% | 14.1%”arXiv 2412.14161v3 Table 1
- Llama 3.3 70B 6.9%“Llama-3.3-70b | 6.9% | 12.8%”arXiv 2412.14161v3 Table 1
- 7 models“seven rows: Gemini-2.5-Pro, Claude-3.7-Sonnet, Claude-3.5-Sonnet, Gemini-2.0-Flash, GPT-4o, Llama-3.1-405b, Llama-3.3-70b”arXiv 2412.14161v3 Table 1
- a simulated software company with internal sites and data“a self-contained environment with internal web sites and data that mimics a small software company environment”arXiv 2412.14161 abstract
- institutions CMU and Duke“Carnegie Mellon University, Duke University”arXiv 2412.14161v3
- version 3, September 2025“v3: September 10, 2025”arXiv 2412.14161
- arXiv identifier 2412.14161“arXiv:2412.14161”arXiv